From fine detail to coarser steps
The previous chapter asked a simple question: why does a language model need so much memory? Most of it is taken up by the model's weights. These are billions of numbers adjusted during training and used in its calculations. The model also needs working memory while generating an answer and space for information about the text processed so far.
We used Qwen3.8-27B as an example. It has roughly 27 billion weights. If each number were stored in 16 bits – two bytes – the weights alone would take up about 54 gigabytes. Not every computer has that much fast memory to spare for a model. Yet there are versions that run on some consumer devices. How is that possible?
Part of the answer is quantisation. It does not remove the weights. Instead, it stores approximate values using less space. The numbers used by the model change. So why can it still produce useful results? And when do those changes matter?
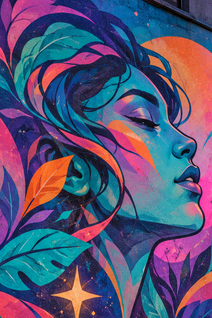
Picture a colourful graffiti mural. With many shades, the transitions across the face and hair are fine. With only a few colours available, you can still recognise the face and hair, but subtler differences disappear. The comparison directly below shows this visually. No pixels have been removed; the differences between the colours have become coarser.
 16 bits
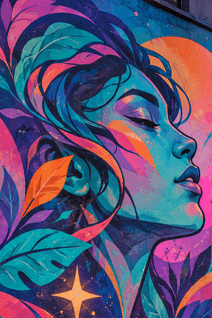 8 bits
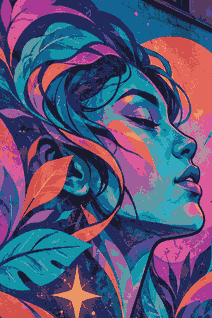 4 bits
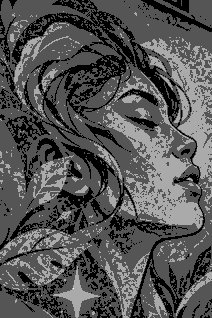 2 bits · four shades of grey
Image content as text
All four panels show the same close crop of a graffiti mural: a face in profile with closed eyes, flowing hair and leaves. The first two panels are colourful and differ only slightly. The third has larger areas of solid colour and fewer subtle transitions. The fourth uses only four shades of grey. The face and hair remain recognisable, but many small differences in colour and brightness have disappeared. This is a visual analogy for coarser steps, not output from quantised language models.
Weights are numbers rather than colours. Imagine one with the value −0.723. In a deliberately simplified example, the stored version might represent it as approximately −0.72. Here, precision means how finely the stored values can distinguish one number from another. The number is approximated, much like rounding to fewer decimal places. A particular bit count does not, however, correspond to a fixed number of decimal places.
The software assigns smaller stored codes to groups of weights and uses a conversion rule to associate those codes with approximate numerical values. Negative values and values above one are possible too. Fewer bits for a code mean fewer available steps within its chosen range. How well that works depends on the method and on the weights themselves. [1] [2]
Why can the model still calculate?
In How does an LLM work?, we described how a model scores possible next pieces of text and selects a continuation. Here we look one step earlier in that process: where do those scores come from after the weights have been rounded?
The weights are still present. The model processes the same preceding text and now uses approximate numbers in its calculations. It still produces scores for the same possible text pieces. Using fewer bits to store individual weights does not reduce the model's vocabulary to a handful of choices. It can change the scores assigned to those choices.
Consider a tiny, invented comparison. Before quantisation, choice A scores 8.2, well ahead of B at 4.1. Afterwards they score 8.0 and 4.2: the values have changed, but A remains ahead. In another case, A and B start very close, at 8.2 and 8.1. After approximation they might score 8.0 and 8.2, reversing the order. These made-up scores are not probabilities or measurements from Qwen. They illustrate what can happen, not how often it happens.
How much space can it save?
For roughly 27 billion weights, the arithmetic for the weights alone is straightforward:
| Storage per weight | Calculated space for 27 billion weights |
|---|---|
| 16 bits | about 54 GB |
| 8 bits | about 27 GB |
| 4 bits | about 13.5 GB |
| 2 bits | about 6.75 GB |
This is an idealised calculation for weights, not a list of ready-made model files. Nor does it promise the same quality or speed at every level. The two-bit row shows the arithmetic at an extreme reduction; it does not establish that a useful two-bit version of this particular model exists.
The model files of the Qwen3.8-27B version examined locally occupy about 30.9 GB, not 27 GB. Many of its weights use a compact format, but some components retain more detail, and the conversion requires additional data. The running model also needs working memory and the KV cache described in Why does an LLM need so much memory?. A smaller model file is therefore not a complete account of its memory use. The file size was measured from the local snapshot; the public model configuration documents the mixed numerical formats. [3]
Smaller is not automatically as good or as fast
Saving memory comes at a price: the weights are approximate. That can change the model's answers. Whether the difference is noticeable depends on the model, the quantisation method and the task. The bit count alone cannot tell you how well a particular version will answer; its results have to be tested. [2] [4] [5]
A smaller file is not automatically faster either. It can help if the model then fits into available fast memory. But the software and hardware must be able to handle the format efficiently. Testing the actual model on the intended computer tells us more than a rule such as “four bits is faster than eight”. [1] [2]
Quantisation addresses a concrete problem: it can make a model's weights small enough to run, or to stay in fast memory, on a suitable computer. It does not take away the model's possible next text pieces, and it cannot turn an incorrect claim into a correct one. It trades storage space for approximate weights whose effects need to be judged in the specific model.
Deeper into the Rabbit Hole
For more detail on how the methods and hardware work together, these texts and videos are a useful next step:
Texts
- Maarten Grootendorst: A Visual Guide to Quantization – clear visual steps and numerical examples; the later sections are more technical than this chapter.
- llama.cpp: Quantize – documented sizes, quality measurements and speeds for specific local formats.
- Google AI Edge: Post-training quantization – why the format and supported operations matter when running a model.
Videos
- Matt Williams: Optimize Your AI – Quantization Explained – local models, bit levels and choosing a suitable version.
- IBM Technology: LLM Compression Explained – memory, speed and the limits of compression.
Sources
- Google AI Edge: Post-training quantization.
- ggml-org / llama.cpp: Quantize.
- Hugging Face: configuration of the Qwen3.8-27B version examined here. The roughly 30.9 GB of model files was measured from the local snapshot.
- Dettmers et al.: LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale.
- Frantar et al.: GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers.